Showing posts with label Database. Show all posts

Sunday, May 22, 2011

PostgreSQL - strange database server errors under Windows

I often use PostgreSQL as a database server for my web applications which are usually deployed under Tomcat. PostgreSQL and Tomcat are registered as system services which starts automatically when Windows starts. 

In one of my application I have about 50 different databases with connection pools for each database, where each pool has about 10 connections opened. So I have about 500 connections opened for requests. Each opened connection is visible as a separate postgres.exe process in the system next to the own PostgreSQL processes also visible as postgres.exe (usually 5 processes). Sometimes under Windows XP Prof. SP 3 I saw PostgreSQL stop working and in the server logs there were errors like:
  •  java.net.SocketException: No buffer space available (maximum connections reached?): recv failed
or:  
  • server process (PID XXXX) was terminated by exception 0xC0000142 HINT:  See C include file "ntstatus.h" for a description of the hexadecimal value.
--------------------------------------------
No buffer space available error:

"Maximum connection reached" may suggest that we set too low value of max_connections in postgresql.conf file. Let's assume that settings for connections amount and required memory are OK for the server, but the problem is still visible from time to time.

The first thing to be checked is amount of short-lived ports (ephemeral). Those ports are used by applications during their normal work. They are opened and live until certain application works, in comparison to server application ports that are typically open for the entire time that the server computer is running. They are assigned automatically from predefined range. Range differs between operating systems:

a) Windows 2000 -> from 1024 to 5000
b) Windows 2003 Server -> from 1024 to 5000
c) Windows XP (all service packs) -> from 1024 to 5000
d) Windows Vista -> from 49152 to 65535
e) Windows 2008 Server -> from 49152 to 65535
f) Windows 7 -> from 49152 to 65535
g) Linux kernels -> from 32768 to 61000 (see /proc/sys/net/ipv4/ip_local_port_range)

If the available pool of ephemeral ports is exahsuted we see Windows WSAENOBUFS error (no buffer space, code 10055). In order to check for exceeded range, we have to see how many processes are running in the system and how many ports they are opening - we can use free TCPView application. We can kill the process that causes exceeding or we can increase the range of ephemeral ports. If we want to increase it, we have to change a registry entry named maxUserPort in:

HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Services\Tcpip\Parameters\maxUserPort
 
If that registry entry does not exist it means that system uses default value (see above) and we have to create this entry. Then we have to set a proper value for that entry (REG_DWORD) from the range 5000 to 65534. 

The second thing to be checked is limit of half-opened TCP/IP connections (connection with state SYN-RCVD). When this limit is exceeded, TCP/IP starts up SYN flooding attack protection (when SynAttackProtect is enabled). This limit differs between operating systems:

a) Windows 2000 Workstation -> 500
b) Windows 2000 Server -> 100
c) Windows Server 2003 -> 500 
d) Windows XP SP 1 -> 100
e) Windows XP SP 2, SP3 -> 10
f) Windows Vista SP 1 -> 10
g) Windows Vista SP 2 -> limit removed (not implmented = unlimited)
h) Windows Server 2008 SP 1 -> 10
i) Windows Server 2008 SP 2 -> limit removed (not implemented = unlimited)
f) Windows 7 -> limit removed (not implemented = unlimited) 

We can use mentioned TCPView application to check for half-opened TCP connections. This limit can be increased by changing the registry entry named TcpMaxHalfOpen in:

HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Services\Tcpip\Parameters\TcpMaxHalfOpen

If that registry entry does not exist it means that system uses default value (see above) and we have to create this entry and then manualy assign new value.

Under Windows Vista SP2, Windows 7 or Linux I did not see that error.

--------------------------------------------
0xC0000142 error:

This problem is not so easy to explain, although I was able to fix it. The error code means that "A dynamic link library (DLL) initialization routine failed." I am not sure what exacly causes this... 

In my case under Windows XP Prof. SP 3, when I started my application and number of postgres.exe processes was about 100 (it should be about 500, see description at the top) the whole database server process was suddenly terminated and I saw second mentioned error (with error code 0xC0000142) in the logs. The most important part here is that PostgreSQL service, which spawned many postgres.exe child processes, was registered under LOCAL SYSTEM account, without "Allow Service to Interact with Desktop" option set.

It seems that this problem is not only connected with PostgreSQL. It is general problem with services and their subprocesses (see this and that article). From the information found the problem my be connected with so-called desktop heaps (see more here and here). Some people having similar problems with many subprocesses did the workaround by setting "Allow Service to Interact with Desktop" to true for their LOCAL SYSTEM services. I was able to fix it under Windows XP Prof. SP 3, by registering PostgreSQL service for regular user account instead of LOCAL SYSTEM (see "Long Version" from my article about manual installation of PostgreSQL how to do this). I also checked this under Windows Vista SP2 and Windows 7 - it works OK there, even under LOCAL SYSTEM account. Under Linux I did not see that error.

I did not try to assign more desktop heap from default for Windows XP SharedSection=1024,3072,512 (2nd or 3rd value needs to be changed) and then try it again to run under LOCAL SYSTEM without "Allow Service to Interact with Desktop". Perhaps this might also help.

Tuesday, April 26, 2011

JSF 2, Spring 3, JPA (Hibernate 3), PostgreSQL, c3p0 - everything together (part 2 of 2)

Note: below description uses Eclipse Indigo, Tomcat 7.0.28, MyFaces 2.1.7, Spring Framework 3.1.1, Spring Security 3.1.0, Hibernate 3.6.10 (Final), PostgreSQL 9.1.

Requirements:
  • running database and complete project with all required libraries integrated, described in previous post (can be found here)

Step 4 (continued): configuration files - faces-config.xml.

Comparing to a JSF 2.0 project with Spring integrated, only applicationContext.xml file will be changed - web.xml and faces-config.xml files will be the same. We need to add below code into applicationContext.xml:
<bean id="pooledDataSource" 
 class="com.mchange.v2.c3p0.ComboPooledDataSource" destroy-method="close"> 
 <property name="driverClass" value="org.postgresql.Driver" />
 <property name="jdbcUrl" value="jdbc:postgresql://localhost:5432/bikes"/>  
    <property name="user" value="postgres"/>  
    <property name="password" value="pgpass"/> 
    <property name="maxPoolSize" value="10" />
 <property name="maxStatements" value="0" />
 <property name="minPoolSize" value="5" />  
</bean>
 
<bean id="JDBCDataSource" 
 class="org.springframework.jdbc.datasource.DriverManagerDataSource" >
 <property name="driverClassName" value="org.postgresql.Driver"/>
 <property name="url" value="jdbc:postgresql://localhost:5432/bikes"/>
 <property name="username" value="postgres"/>
 <property name="password" value="pgpass"/>
</bean>
 
<bean id="entityManagerFactory"
 class="org.springframework.orm.jpa.LocalContainerEntityManagerFactoryBean">
 <property name="jpaVendorAdapter">
  <bean class="org.springframework.orm.jpa.vendor.HibernateJpaVendorAdapter" >
   <!-- 
   Specific properties for Hibernate are in persistence.xml file, 
   but also can be placed here and removed from persistence.xml file.  
   -->
  </bean>
 </property>
 <property name="dataSource" ref="pooledDataSource" />
 <property name="persistenceUnitName" value="persistenceUnit"/> 
</bean>

<bean 
 class="org.springframework.orm.jpa.support.PersistenceAnnotationBeanPostProcessor" />

<bean name="transactionManager" 
 class="org.springframework.orm.jpa.JpaTransactionManager">
 <property name="entityManagerFactory" ref="entityManagerFactory" />  
</bean>

<tx:annotation-driven />
Note that this approach is similar to situation when plain Hibernate API is used with Spring: JPA's EntityManagerFactory is like Hibernate's SessionFactory, JPA's EntityManager (obtained from EntityManagerFactory) is like Hibernate's Session (obtained from SessionFactory). JPA's EntityManager is injected into Repositories (with the help of Spring's PersistenceAnnotationBeanPostProcessor class), while Hibernate's Session was injected into DAO's (with the help of Spring's HibernateDaoSupport class exteneded by each DAO). JPA's TransactionManager (built on EntityManagerFactory) is like Hibernate's HibernateTransactionManager (built on SessionFactory).
JPA's Repositories and Services are similar to oldschool DAOs and Facades. Repositories are injected into Services, while DAOs are injected into Facades.

Please note that I defined here two datasources: a basic one without connection pool (JDBCDataSource) and second one using c3p0 as a connection pool (pooledDataSource).


Step 5: configuration files - persistence.xml

In addition JPA uses a special configuration file named persistence.xml. This file contains additional settings for JPA vendor. The location of this file is described in this article. In order to have this file inside WEB-INF/classes/META-INF/persistence.xml under Eclipse, I created a directory "config" where I put META-INF subdirectory with persistence.xml file inside. Then I select the directory "config" to be used as a source directory. This means that content of "config" directory will be on classpath, and for a web application during a build time it will be moved into WEB-INF/classes. Note that I also added there log4j config file:


Persistence.xml file contains some specific settings for Hibernate (as JPA vendor):
<?xml version="1.0" encoding="UTF-8" ?>
<persistence xmlns="http://java.sun.com/xml/ns/persistence"
 xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
 xsi:schemaLocation="http://java.sun.com/xml/ns/persistence
        http://java.sun.com/xml/ns/persistence/persistence_1_0.xsd"
 version="1.0">

 <persistence-unit name="persistenceUnit" transaction-type="RESOURCE_LOCAL">
  <properties>   
     <property name="hibernate.dialect" value="org.hibernate.dialect.PostgreSQLDialect" />
     <property name="hibernate.show_sql" value="true" />
    </properties> 
 </persistence-unit>
</persistence>


Step 6: configuration files - log4j.properties


As I wrote before we will use Log4j instead of Hibernate's default SLF4j. Lets's log everything we can (we can see how Hibernate opens/closes connections, how connections are taken from the pool, how Spring manages transactions and so on):
log4j.appender.A1=org.apache.log4j.ConsoleAppender
log4j.appender.A1.layout=org.apache.log4j.PatternLayout
log4j.appender.A1.layout.ConversionPattern=%d{HH:mm:ss,SSS} %-5p [%c] - %m%n
log4j.rootLogger=info,A1

log4j.logger.com.mchange.v2=DEBUG 
log4j.logger.org.hibernate=DEBUG
log4j.logger.org.springframework=DEBUG

Step 7: database entities.

As shown at the beginning of previous post, we had only one entity represented by the class Bike.java. Instances of Bike.java where created inside Spring service named bikeDataProvider (BikeDataProviderImp.java). Now we have a database with tables Bike, Bike_Category, Account and Role. For each table we should create one class (note: this is the simplest mapping one table to one class - there are other way to map tables to classes).


Bike entity:
package com.jsfsample.model;

@Entity
@Table(name="bike")
public class Bike implements Serializable {

 private Integer id;
 private BikeCategory category; 
 
 @Id
 @GeneratedValue(strategy=GenerationType.IDENTITY)     
 @Column(name="bike_id")
 public Integer getId() {
  return id;
 }
 public void setId(Integer id) {
  this.id = id;
 }
 
 @ManyToOne
 @JoinColumn(name="bike_category_id") 
 public BikeCategory getCategory() {
  return category;
 }
 public void setCategory(BikeCategory category) {
  this.category = category;
 }
 
 // rest of columns
}
Bike_category entity:
package com.jsfsample.model;

@Entity
@Table(name="bike_category")
public class BikeCategory {
 
 private Integer categoryId;
 
 @Id
 @GeneratedValue(strategy=GenerationType.IDENTITY)
    @Column(name="bike_category_id")
 public Integer getCategoryId() {
  return categoryId;
 }
 public void setCategoryId(Integer categoryId) {
  this.categoryId = categoryId;
 }
 // rest of columns
}
Account entity:
package com.jsfsample.model;

@Entity
@Table(name="account")
public class Person {
 
 private Integer accountId;
 private Role currentRole;
 
 @Id
 @GeneratedValue(strategy=GenerationType.IDENTITY)
    @Column(name="account_id")
 public Integer getAccountId() {
  return accountId;
 }
 public void setAccountId(Integer accountId) {
  this.accountId = accountId;
 }
 
 @ManyToOne
 @JoinColumn(name="role_id") 
 public Role getCurrentRole() {
  return currentRole;
 }
 public void setCurrentRole(Role currentRole) {
  this.currentRole = currentRole;
 }
 // rest of columns 
}
Role entity:
package com.jsfsample.model;

@Entity
@Table(name="role")
public class Role {

 private Integer roleId;
 
 @Id
 @GeneratedValue(strategy=GenerationType.IDENTITY)
    @Column(name="role_id")
 public Integer getRoleId() {
  return roleId;
 }
 public void setRoleId(Integer roleId) {
  this.roleId = roleId;
 }
 // rest of columns
}
Note how classes are mapped to tables (using @Table(name="...")) and how fields are mapped to columns (using @Column(name="...")). We also mapped many-to-one relations between tables using @ManyToOne annotation with proper joim column name. Note also how primary keys are generated - we do not use PostgreSQL sequence (GenerationType.SEQUENCE) - PostgreSQL supports SERIAL data type for primary keys, which actually hides sequences (see this link).

Step 8: repositories and services.

Spring repositories are similar to DAO. All database interactions is done insde them. As an example, let's look inside repository resposnible for loading and saving bikes - BikesDAOImpl.java:


package com.jsfsample.repositories.impl;

@Repository("BikesRepository")
public class BikesDAOImpl implements BikesDAO {
 
 private EntityManager em = null;
 
 @PersistenceContext
 public void setEntityManager(EntityManager em) {
  this.em = em;
 }
 
 @Override
 public Bike loadSelectedBike(Integer bikeId) {
  return em.find(Bike.class, bikeId);
 }
 // other methods for saving bike and loading bike for given category

}

This repository is used in Spring's service named bikeDataProvider (BikeDataProviderImpl.java):


package com.jsfsample.services.impl;
...
@Service("bikeDataProvider")
public class BikeDataProviderImpl implements BikeDataProvider {

 @Resource(name="BikesRepository")
 private BikesDAO bikesRepository;
 
 @Resource(name="DictionaryRepository")
 private DictionariesDAO dictionaryRepository;

 public Bike getBikeById(Integer id){
  return bikesRepository.loadSelectedBike(id);
 }
 
 @Transactional
 public void add(Bike newBike, Integer categoryId) {
  BikeCategory categorySelected = dictionaryRepository.loadBikeCategroryById(categoryId);
  newBike.setCategory(categorySelected);
  bikesRepository.saveBike(newBike);
 } 
 
 // other methods using repositories
}
Similar solution is used for account (person) repository which is then used in Spring's Security service named userDetailsService (UserDetailsServiceImpl.java). Note how easy is to execute a method within database transaction - just use @Transactional annotation and voila.

That's all about adding JPA into Spring-based JSF2 sample application.

The rest of application code (web pages, JSF managed beans) are the same as in pure Spring example project - we only modified services by providing repositories.

How to test it? After deploying application on the server and starting the server, we have to open a browser and type in URL:

http://localhost:8080/JSF2FeaturesSpringJPA


-------------------------------------------
Download source files:
Note: make sure that Java, Eclipse and Tomcat are properly installed and configured for running the project (additional configuration may be required if different directories are used).

Eclipse complete sample project is here (with all required libraries). The sample project is a ready to run application which contains JPA (Hibernate), Spring (with Spring Security). You can also download a war file located here (just copy it inside webapps folder in Your Tomcat and start Tomcat with the script startup.bat). Make sure that before doing this You created required database and PostgreSQL server is up and running (You can check access using pgAdmin III).

Wednesday, March 09, 2011

JSF 2, Spring 3, JPA (Hibernate 3), PostgreSQL, c3p0 - everything together (part 1 of 2)

Note: below description uses Eclipse Indigo, Tomcat 7.0.28, MyFaces 2.1.7, Spring Framework 3.1.1, Spring Security 3.1.0, Hibernate 3.6.10 (Final), PostgreSQL 9.1.

Requirements:
  • a working example of JSF 2.0 application with Spring Framework and Spring Security integrated (can be found here)
  • installed PostgreSQL database (simple installation variant described here)
You will learn:
  • how to use database for loading and storing the data in the sample JSF 2.0  application
  • how to access the database from the application using JPA (Hibernate) and Spring
  • how to optimize database access by using connection pool (c3p0)
It is a high time to create a real working example with a database. Sample application used in previous posts use no database. We had Spring's managed service named bikeDataProvider acting as a database - all bikes data were created in that service during startup, all bikes data were retrieved from that service, even new bike data were stored internally in the service:
package com.jsfsample.services.impl;
...
@Service("bikeDataProvider")
public class BikeDataProviderImpl implements BikeDataProvider {

 private List<Bike> bikes;

 @PostConstruct
 private void prepareData(){
  bikes = new ArrayList<Bike>();
  
  // MTB
  Bike mtb1 = new Bike();
  mtb1.setId(1);
  mtb1.setName("Kellys Mobster");
  mtb1.setDescription("Kellys Mobster, lorem ipsut...");
  mtb1.setPrice(6500);
  mtb1.setCategory(1);
  
  // ... rest of mock bikes created here
 }
 
 public List<Bike> getBikesByCategory(Integer categoryId, boolean onlyWithDiscount) {
  // returns bikes by given category
 }
 
 public Bike getBikeById(Integer id){
  // returns certain bike for its details
 }

 @Override
 public void add(Bike newBike) {
  // add new bike 
  bikes.add(newBike);
 }
}
The same method of creating mock data was used in Spring's managed service named userDetailsService - users and their authorities were created directly inside the service:
package com.jsfsample.application.impl;
...
@Service("userDetailsService")
public class UserDetailsServiceImpl implements UserDetailsService {

 private HashMap<String, org.springframework.security.core.userdetails.User> users = new HashMap<String, org.springframework.security.core.userdetails.User>();
 
 @Override
 public UserDetails loadUserByUsername(String username) {
  // returns user
 }

 @PostConstruct
 public void init() {
  
  // mocked roles  
  Collection<GrantedAuthority> adminAuthorities = new ArrayList<GrantedAuthority>();
  adminAuthorities.add(new GrantedAuthorityImpl("ROLE_ADMIN"));
  
  Collection<GrantedAuthority> userAuthorities = new ArrayList<GrantedAuthority>();
  userAuthorities.add(new GrantedAuthorityImpl("ROLE_REGISTERED"));
  
  boolean enabled = true;
  boolean accountNonExpired = true;
  boolean credentialsNonExpired = true;
  boolean accountNonLocked = true;
  
  // mocked users with roles
  users.put("admin", new org.springframework.security.core.userdetails.User("admin", "admin", enabled, accountNonExpired,
    credentialsNonExpired, accountNonLocked, adminAuthorities));
  
  users.put("user", new org.springframework.security.core.userdetails.User("user", "user", enabled, accountNonExpired,
    credentialsNonExpired, accountNonLocked, userAuthorities));
 }
}
In both cases all data are created in the method annotated with @PostConstruct. That annotation means, that method will be invoked first after creating an instance of a class (in this case Spring creates instances of those service classes).

Our objective is to remove that mocked data created explicite in the services classes and replace them with data coming from real database.

Step 1: we need database structure:
CREATE TABLE "role" (
 role_id SERIAL NOT NULL,
 name VARCHAR(32),  
 CONSTRAINT role_pk PRIMARY KEY (role_id)
);

CREATE TABLE "account" (
 account_id SERIAL NOT NULL,
 role_id INTEGER NOT NULL,
 login VARCHAR(32),
 password VARCHAR(32),
 CONSTRAINT account_pk PRIMARY KEY (account_id),
 CONSTRAINT role_id_fk FOREIGN KEY (role_id) REFERENCES role(role_id)
);

CREATE TABLE "bike_category" (
 bike_category_id SERIAL NOT NULL,
 name VARCHAR(32),  
 CONSTRAINT bike_category_pk PRIMARY KEY (bike_category_id)
);

CREATE TABLE "bike" (
 bike_id SERIAL NOT NULL,
 bike_category_id INTEGER NOT NULL,
 name VARCHAR(32),
 description TEXT,
 price numeric(10,2),
 discount_price numeric(10,2),    
 CONSTRAINT bike_pk PRIMARY KEY (bike_id),
 CONSTRAINT bike_category_fk FOREIGN KEY (bike_category_id) REFERENCES bike_category(bike_category_id)
);
This is very simple database with two many-to-one relations: many users belongs to (have) one role and many bikes belongs to (have) one category. Of course in real world user would have many roles, so we would use many-to-many relation, but I decided to use many-to-one to simplify it.
Tables account and role will be used by Spring Security - they store users and their authorities (roles). Tables bike and bike_category are the "heart" of bike store.

Step 2: when structure is ready, it is time to insert some sample data:
INSERT INTO role (name) values ('ROLE_ADMIN'); -- id 1
INSERT INTO role (name) values ('ROLE_REGISTERED'); -- id 2

INSERT INTO account (role_id, login, password) values (1, 'admin', 'admin'); -- ROLE_ADMIN
INSERT INTO account (role_id, login, password) values (2, 'user', 'user'); -- ROLE_REGISTERED

INSERT INTO bike_category (name) values ('Mountain'); -- id 1
INSERT INTO bike_category (name) values ('Trekking'); -- id 2
INSERT INTO bike_category (name) values ('Cross'); -- id 3

INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (1, 'Kellys Mobster', 'Kellys Mobster, lorem ipsut...', 6500, null); -- Mountain
INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (1, 'Scott Scale', 'Scott Scale, lorem ipsut...', 18900, null); -- Mountain
INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (1, 'Author Magnum', 'Author Magnum, lorem ipsut...', 17200, 15500); -- Mountain

INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (2, 'Giant Accend', 'Giant Accend, lorem ipsut...', 5000, 4600); -- Trekking
INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (2, 'Merida Freeway', 'Merida Freeway, lorem ipsut...', 2400, 2100); -- Trekking
INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (2, 'Mbike Massive', 'Mbike Massive, lorem ipsut...', 1900, null); -- Trekking

INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (3, 'Giant Roam XR 1', 'Giant Roam XR 1, lorem ipsut...', 3900, null); -- Cross
INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (3, 'Cannondale Quick Cx', 'Cannondale Quick Cx, lorem ipsut...', 4999, null); -- Cross
INSERT INTO bike (bike_category_id, name, description, price, discount_price) values (3, 'Cube Cross', 'Cube Cross, lorem ipsut...', 4500, 4200); -- Cross

Step 3: adding required libraries into project.


Comparing those libraries with libraries from clean JSF 2.0 project (look here) or libraries from JSF 2.0 project with Spring (look here) we have extra libraries here: Hibernate libraries marked green, Spring JPA libraries marked red and some third party libraries marked blue. Those blue libraries are:
  • c3p0 libraries for connection pool
  • log4j library and bridge library from sl4j to log4j - Hibernate by default uses sl4j, but we would like to use log4j
  • JDBC driver for PostgreSQL
Step 4: configuration files - will be continued in next post.

-------------------------------------------
Download source files:
The complete working example of mentioned application which will contain all described issues, will be available in the last (second) article of this serie.

Wednesday, February 24, 2010

"My databse is slow" - part 3: some technical stuff

Note: below description uses PostgreSQL 8.3.7.

In the previous two articles I tried to show what can affect the overall performance of the database and how important are indexes.
If we assume that the database is normalized, memory settings for the server are ok and we have indexes, the only way to check the performance is monitoring the query plans. Therefore I would like to return once again to the query plans and look at them with more details.

From the previous post, we know that we can generate plans for queries using two commands. These commands are:
  • EXPLAIN SQL_command
  • EXPLAIN ANALYZE SQL_command - this command is a variant of the first with small difference: examined query is executed and EXPLAIN ANALYZE returns the real execuion time.
Using the test database from the previous post, let's see the query plan for the following SQL command:

select * from customers where lname = 'Cervantes';

To see the query plan, execute those two commands:

vacuum analyze;
explain select * from customers where lname = 'Cervantes';

Query plan that has been generated for this query is as follows:


Always we are most interested in "the highest" line of displayed plan - it shows the total cost of the query execution, after all other internal operations for more complex queries (eg joins, sorts, etc.).

In our case we have: (cost: 4.51 .. 59.47 rows = 33 width = 18). What does it mean?
  1. cost: 4.51 .. 59.47 - this is an interval defining total execution time measured in special units called disk page fetches - these units are not seconds nor other units of time. First number estimates time needed to retrieve first row in the result, second estimates total cost of returning all rows in the result. The calculation of this value is "higher mathematics", especially if the query uses more techniques than primitive table sequential scanning - which is the easiest and can be easily calculated. Unfortunately, but only for primitive examples like "select * from some_table" (without the use of indices to be 100% sure that the scan will be performed sequentially and without any query conditions "where"), You can find over the Web some examples of calculating these values. Those who are interested in more details and technical stuff, should visit this page
  2. rows = 33 - this is estimated number of rows returned by a query.
  3. width = 18 - this is estimated size (in bytes) of all the returned rows

Above data are obtained on the basis of statistics located in a special system tables. There are two tables of statistics which are crucial for the query planner:
  1. pg_class - contains information about certain database relations (tables, indexes, etc.), i.e. their location and size.
  2. pg_stats - contains information about the data stored in tables, i.e. the most common values, the frequency of common values occurrence.
Let's see what are the statistics for the table "customers", and what is their impact on some elements of the query plan for above query about user "Cervantes".


Returned data mean that the table "cutomers" has 10.000 records and is located on 62 "pages".


Returned data are based on some statistical data for all the columns in the table "cusotmers" and their content. It is specified which values are most popular, what is their frequency, and amount of values which are different from each other.
What is the meaning of this data in the context of our query about "Cervantes" user?

pg_class - is the basis in calculating the cost of the query execution. For our "Cervantes" query  in the case of sequential scan (if there were no index on the "lname" field in the Customers table), we would calculate the cost from the formula:
(relpages * SEQ_PAGE_COST) + (reltuples * CPU_TUPLE_COST) + (relpages * CPU_OPERATOR_COST)
Capitalized names are costs of arbitrary operation - the are defined in postgresql.conf. Unfortunately (or "fortunately"), our query uses indexes, so the calculation of the cost is a bit more complicated (task for volunteers, formulas are here, You only have to to be familiar with the concepts of "last recently used buffers" (LRU) and Mackert-Lohman formula ;-)).

pg_stats - allows to estimate the number of rows returned in a query using given logical condition (in our case: "where lname = 'Cervantes'"). In our case for the "Cervantes" query we are lucky - "Cervantes" occurs directly in the list of most common surnames, and also is known for its occurrence. The number of rows returned is calculated using the formula:
relpages * selectivity
where:
selectivity = most_common_freqs["Cervantes"]
Hence we get:
10000 * 0,00333333 = 33
And what if we are looking for value which is not in the column "most_common_freqs"? Then the formula has a different form:
selectivity = (1 - sum(most_common_freqs))/(num_distinct - num_most_common_vals)
Calculating selectivity value for the name "Smith", I leave for volunteers as usually ;-). Remember that first You have to execute "vacuum analyze" and then view statistics and then the query plan.

-------------------------------------------- 
Some notes about the statistics:

The content of statistics tables is generated based on random samples taken from the tables in the database. Generating (and therefore refreshing) full statistics takes place during the execution of the VACUUM ANALYZE command. Hence, it is very important to run this command periodically to ensure that statistics for the planner are up to date. Therefore, before showing the above example the first command executed by me was VACUUM ANALYZE in order to query plan be based on the most reliable statistics.
It should be noted that next execution of this command can generate a slightly different statistics, so query plan for the same query may be slightly different (in terms of cost and estimated number of rows). This is because of mentioned random samples taken for calculations.

--------------------------------------------
A few final notes about performance

I can say that the general rule to optimize query execution time is as follows:
"There is no certain way to increase performance in all cases. The best method is trial and error."
In practice it means to try to generate different query plans (in addition to that which is generated by default) and select those with the best execution time. These attempts usually involve forcing the query planner  to behave in different way which leads to a different query plan. This can be achieved through:

1. Forcing the query planner to use an index (often the index exists but is not used by the planner). This can be done for example by:

  • switching off a global sequential scans by setting enable_seqscan = off in postgresql.conf file
  • partial indexes (conditional) - You can create a conditional index for the most frequently returned data in column
  • indexes using multiple fields (watch out for the order - the order of fields in the index should be the same as the order of fields in queries)
  • some SQL tricks related to change the query selectivity, for example using LIMIT, ORDER BY or trailing condition AND TABLE_ID = TABLE_ID (where TABLE_ID is a master key in the table)
2. Changing the order of joining multiple tables, for example executing "(A join B) join C" can be different than executing "A join (B join C)" - this is similar to a problem of  "optmial matrix-chain multiplication".
3. Using stored procedures, views, breaking huge query into a number of smaller queries .

Interesting fact (found over the Web):
In order to monitor the progress of executing a long query to the database (a really long time, not a few seconds) you can create a sequence with the value set to 1 (eg, the sequence "monitor_seq") and add it to executing query:


select nextval('monitor_seq'), column1, column2....

Executing:

select currval('monitor_seq');

at the time of running the long query will show us the progress.

Tuesday, January 05, 2010

"My database is slow" - part 2: indexes.

Note: below description uses PostgreSQL 8.3.7.

This article is a continuation of previous one about database performance.
Suppose we have a database that is normalized to our needs, the memory of the server was also quite reasonably allocated, we are using a connection pool and we did not change the default transaction isolation level for our database - but the database still is not a "speed daemon". What can You do in this situation? Did we miss something?

You can look inside the database giva a closer look on specific operations performed on the data to determine which operations cause performance degradation and possibly "help" them perform faster. As the sample database I will use PostgreSQL - I will examine its specific mechanisms to check and improve performance. This will be only an outline of what can be done (based on crude example), because the topic is so large that it may well be placed on a separate dedicated blog.

Requirements:
  • installed PostgreSQL (description here)
  • a test database with sample data - just to show how PostgreSQL performs a very simple SQL opeartions
Let's consider a very simple database for some online store with two tables: customer table (called Customer) and customers' orders table (called Order). Just open pgAdmin and execute this SQL command:


CREATE DATABASE store ENCODING = 'UTF8';


Then connect to database "store" and run this SQL commands:


CREATE TABLE customers
(
customer_id INTEGER,    
fname VARCHAR(32),
lname VARCHAR(32) NOT NULL,
CONSTRAINT customer_pk PRIMARY KEY(customer_id)
);

CREATE TABLE orders
(
order_id INTEGER,
customer_id INTEGRE NOT NULL CONSTRAINT customer_order_fk REFERENCES customers(customer_id),
description TEXT,
price NUMERIC(7,2),    
CONSTRAINT order_pk PRIMARY KEY(order_id)    
);

For simplicity, here I do not use a SERIAL field to hold primary keys - just ordinary integer with constraint. Now we should fill the database with some sample data: lets put about 10 000 records to Customers table and 30 000 records to Orders table.  That is rather huge amount of data. How can we do it?
The best way is to write a Java program that generates a file with proper SQL INSERT statements for each table - this is homework for You ;-)
I wrote simple program which takes popular first names for males and popular first names for females, then takes popular surnames from here and combines them together to produce 10.000 "people". Having those records and knowing their customer_id (that's why I used ordinary integer field - just to write a program) my program generated random 30 000 orders for those customers.

And now suppose we want to retrieve all customers named Smith and we want to see all orders for each customer Smith. We need two queries:


select * from customers where lname = 'Smith';
select * from orders join customers on orders.customer_id=customers.customer_id where customers.lname = 'Smith';

In my case, the first query returns just 9 customers named Smith (from total of 10 000) and 30 orders (from total of 30 000) for all 9 "Smiths".

Okay, we have SQL commands - but how can we check their execution time on a database? PostgreSQL provides two commands that show details about executed commands:
a) EXPLAIN SQL_command
b) EXPLAIN ANALYZE SQL_command - this command is a variant of the first with small difference: examined query is executed and EXPLAIN ANALYZE returns the real execuion time.

Before we show an example of above commands execution, some technical information about the process of executing the query by PostgreSQL: when the PostgreSQL server receives SQL command from client application, the query string is passed to the query parser that checks for syntax errors. If everything is ok, parser based on the query creates a structure called the query tree. Then, this structure is passed to the query planner which generates all possible query plans and chooses the shortest one from them. This plan is passed to the executor who performs the query and returns the records in the manner described in query plan.
Mentioned EXPLAIN command displays the details of the plan chosen by the planner as the shortest one. Let's see the result of executing EXPLAIN ANALYZE for the queries about users Smith:


Because reading query plans and their details is a separate art, we will focus on the actual run time (visible as a Total Runtime, respectively 1,482 ms for the first question, and 16,552 ms for the second question).

Lets provide indexes for the fields we are searching for and for the fields where the join operation is performed. In our case it will be:
a) the lname column of the Customers table - create index with the command: 

CREATE INDEX lname_index ON customers USING btree (lname);

b) the foreign key column in Orders table (the column cutomer_id) - create an index using the command: 

CREATE INDEX customer_fk_index ON orders USING btree (customer_id);

Note:
After You create indexes, You have to refresh the statistics used by database planner to calculate the optimal query plan. This is done by running VACUUM ANALYZE command. After executing this command, once again execute the EXPLAIN ANALYZE command for our "Smith" queries:


The results of the queries which are several times faster than previously. They are respectively: 0,123 ms (1,482 ms previously), and 0,507 ms (16,552 ms previously).

The advantage is obvious. But whether the index will solve all our problems? Not always. There is no guarantee that the planner will benefit from the index. Sometimes it appears that the sequential table scan can be faster than using an index (such behavior may depend on the "selectivity" degree of certain query). In most cases it is good to have indexes - they can only help.

Monday, October 12, 2009

"My database is slow" - part 1

Note: below description uses PostgreSQL 8.3.7.

Perhaps You often heard complaints that some application is veeeery sloooow. Despite the technology used, bought another X GB of RAM and so on the problem still exists. Sometimes the cause can be very simple - interaction with the database can be a bottleneck and a source of all problems. This can be checked and possibly improved.
Often the developer itself must change something in the database - do not be afraid to say it - hire a database magician cost a lot of money for the company and often the developer becomes a database specialist ;-). Therefore, anyone who changes something in the database must have some knowledge. Otherwise, some ad-hoc changes can cause a lot of performance problems.
What can you do then? Having the database, You can take a closer look on some points:

1. Database normalization (decomposition).

Simply said - making a database to be in the n-th normal form. You may naively believe that "the database engine can handle" somehow our SQL query, without worrying ourselves about performance. Theoretically yes, even nightmarish database schema will work somehow - after all, a bit smarter (than the rest) people formed the principles of relational databases. The problem starts when our application is no longer a primitive data browser which executes the same "select" SQL query all the time. That's why the other smarter people have invented a normalization. For example this allows the database engine not to retrieve 20 columns from one table just to show us only those 2 which we are interested.
For example let's assume that we have a company and we store all the employees in a one big table:

CREATE TABLE employees ( 
id                int4 PRIMARY KEY,
active            boolean, 
first_name        varchar, 
middle_name       varchar, 
last_name         varchar, 
ssn               varchar, 
address1          varchar, 
address2          varchar, 
city              varchar, 
state             varchar(2), 
zip               varchar, 
home_phone        varchar, 
work_phone        varchar, 
cell_phone        varchar, 
fax_phone         varchar, 
pager_number      varchar, 
business_email    varchar, 
personal_email    varchar, 
salary            int4, 
vacation_days     int2, 
sick_days         int2, 
employee_number   int4, 
office_addr_1     varchar,
office_addr_2     varchar, 
office_city       varchar, 
office_state      varchar(2), 
office_zip        varchar, 
department        varchar,
title             varchar,
supervisor_id     int4
); 

And now some Secretary wants to find those people who earn more than 5000 USD:

SELECT first_name, last_name from employees where salary > 5000 ;

Let's assume that the company is a big corporation which employs thousands of people. Database engine must scan entire table, retrieve all columns for people who earn more than 5000 and at the end pefrorm a projection and return only 2 columns - first name and last name.

Note: do not kid ourselves - normalization is not an ideal remedy for performance problems, and sometimes may even contribute to decrease a performance. Why? For example let's take huge reporting queries that collect a lot of cross-sectional data. In the fully normalized database, the amount of join operations between tables can be very large and could have significant impact on performance. Sometimes it is better to have non-normalized parts of database schema, or even have non-normalized redundant data tables (for generating reports) next to normalized parts. There is no silver bullet solution for that - the approach depends on specific problem. 

2. Memory configuration for the server.  

The fact that Your hardware allows You to play latest games, does not mean that the database will work fast. Even 10-th normal form of a database schema and super-optimal queries will not help when server has total memory similar to required by old DOS games. Sooner or later because of lack of memory many I/O disk operation will be performed to compensate memory request. System resources are important. Unfortunately, at this point databases vary widely in terms of available configuration options. "No silver bullet" also applies here - the only way to discover best performance is to tune database memory settings and test it against SQL queries. 

3. Opening connection to the database.

Although the authors of JDBC drivers maintain that connection cost is small and well optimized, we must not forget that after all this is some expense. As an example, consider a typical web application where in every moment a user clicks on different screens, which show him various data. We have to approaches here:
  • maintaining an open connection during user's working time
  • opening connection for each request, performing some database query, returns the result (which is presented to the user) and closing the connection.
First approach is expensive (in terms of resources and performance), second is much better. But when we take into account the large number of users and their actions, total cost of opening and closing connections may have considerable importance. It is worth here to consider using the so-called connection pool - such as Apache DBCP or C3P0. Responsibility for creating/closing of connections goes to connection pool. The pool itself has various configuration options that can increase the efficiency of cooperation with the database application. For example some connections may have been opened after startup and ready to immediate use and so on. 

4. Transaction isolation levels and locks.

Transaction isolation levels have a direct impact on the types of locks used. If You are not sure how to choose the level of transaction isolation, it is better to remain at the default level for a particular database. You have to remember one important thing: the higher isolation level you choose the more subtle and complex lock must be use by the database engine to provide concurrent access to data. Using higher levels of isolation can also cause deadlock occurrence.


Note: You may not agree with mentioned points. They are only my personal subjective choice based on problems and observations during my work. Database performance is a very broad issue dependent on many factors - I pointed only four general issues, but You may find another four or more which will be just as important and necessary.

Wednesday, April 22, 2009

Installing PostgreSQL (hard version)

Note: below description uses PostgreSQL 8.3.7 version installed on 32 bit Windows XP.

In a previous article I presented how to install PostgreSQL using Windows installer. It was quite easy. But ...
There are people that do not play with such ease, what is more, they can not stand when the system is doing something for them in the background, when something is installed - some services, user accounts... They feel insecure, they are suspicious - only the execution of all activities from the command line calms their nerves.

This time, I prepared the description for the people who love technical masturbation and who love to do everything manually and have everything under control. We'll become the PostgreSQL installer and manually execute all the installation steps to get an effect similar to using Windows Installer. So, let's get to work.

Requirements:
  • we are working on Windows XP using account with Administrator rights (or we belong to the Administrators group)
  • database will be installed to C:\Development\PostgreSQL (the same as when using Windows Installer)
  • disable all antivirus/firewall (this one from Windows too)
Step 1: download the version of the installation file (.zip) of PostgreSQL from here. Download the file with the "binaries-no-installer" part in its name.

Step 2: extract the contents of the file from step 1, to C:\Development\PostgreSQL (zip has the pgsql directory and rest of the folders inside it - I recommend to get rid of it and move all subfolders to C:\Development\PostgreSQL - we will have a shorter path). We should get something like this:


Step 3: we need to create an empty directory named "data" in the directory C:\Development\PostgreSQL (along with the rest of the directories from the picture above).

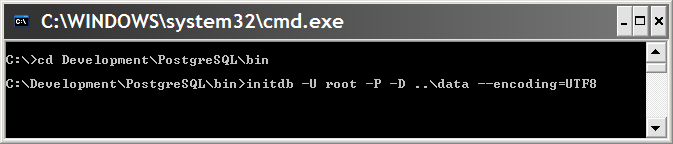
Step 4: create and initialize the database cluster (remember that we are working on the account with Administrator rights). To do this go to the console to the directory C:\Development\PostgreSQL\bin and execute the command:


Desription:
  • option "-U root" means the owner of the database named root - such user account will be created in database (as a superuser)
  • option "-W" means that You will be prompted for a password for this user
  • option "-D .. \ data" means the location of the files for generated database
  • option "- encoding = UTF8" means that the server will have UTF8 encoding by default (each newly created database too!)
After executing this command, we should see sometling like this:


At the bottom, PostgreSQL offers us to run a newly created database using two different commands. It will not work (You can execute those command to see what error is generated) - remember that we are working on account with Administrator rights, and for safety reasons, we can not start and stop the PostgreSQL server on that account. We should create a system service which will run PostgreSQL server process.

--------------------------------------------
The short version:

Step 5: Perform the following command in the console:


That's all. You're done. The service will be created and registered for the Local System Account. This is a special account which can run services, but it is not a typical account with administrator privileges (more info here).

Do not run the service yet.

--------------------------------------------
Long version:

Step 5: continue to imitate the installer. PostgreSQL installer creates a special account with no administrator privileges - so we will also create such account. Acount login and password will be both set to "postgres". We go to Computer Management, then Users:


Now we add new user with login and password postgres:


For the security reason we do not allow to change the password.

We would like now to make "postgres" account able to run the PostgreSQL server. So we need to create and register a special service for this account, which will carry out these operations. Before we do that we need to assign to this account the appropriate permissions to directories where database server is installed.

Step 6: Change the access permissions for the directory server for the postgres account.

And so:
1. Directory C:\Development should only have read permission.
2. Directory C:\Development\PostgreSQL (and its subdirectories) should have all possible permissions.

Step 7: Registering the service.

Using the console go to the directory C:\Development\PostgreSQL\bin and execute there this command:


Description:
  • option -N "PostgreSQL Service" defines the service name
  • option -U postgres says on what account the service is launched
  • option -P postgres gives the password for service account
  • option -D "C:\Development\PostgreSQL\data" tells where database cluster is located (be careful it is very important here to give the full path to the directory "data")

We do not run the service.

--------------------------------------------
Configuration:

Before starting the service must change the basic settings. Move to the directory C:\Development\PostgreSQL\database and open the file postgresql.conf. In this file, You must find and uncomment the following lines:
  • listen_addresses = 'localhost'
  • port = 5432

Now You can start a service in the panel management services.

If everything was done properly, the service should start. If we chose the longer version, in case of trouble with starting the service we should go to the configuration of a service, then select an account for this service and retype password for that service (in our case: postgres)

Theoretically we have the ability to log from the console to the database using the command line (marked red colour):


Thus we should get exactly the same result as using the Windows Installer.

Notes: a short way works ok under Windows XP Prof., should also works ok under Windows Vista - in both systems there is the Local System Account for services. For Windows 2000 You must perform the installation in a long way. For safety, PostgreSQL installer always chooses longer way - it creates an account for the service, then creates sevice itself and registers it to the created account.