Wednesday, October 20, 2010

JSF 2.0 - New features (part 2 of 3)

Note: below description uses Eclipse Indigo, Tomcat 7.0.28 and MyFaces 2.1.7. 

Requirements:
You will learn:
  • resource loading
This is the second post about new features that could be found in JSF 2.0 comparing to JSF 1.x. In the previous post (part 1), I described templating mechanism and simplified navigation model. In this post I would like to focus on the improved resource loading and its capabilities in JSF 2.0.

Resource loading.
What are resources in terms of a web application? It can be images files, JavaScript script files or CSS files used on web pages in the application - so some external files accessible by special tags in the page source. In the JSF application we also name as resources message bundle files.
Just as a short reminder for message bundles:
1. We create message bundle files for each language we would like to support. Then we add some lines into the configuration in faces-config.xml where we define what language will be supported (<locale-config> section) and we define EL access object (<var>msg</var>) for the created message bundle files:


2.  We use message from the bundle files by calling defined EL accessor in the page source, for example:
<h:outputText value="#{msg['top.name']}" />
This approach gives us the most important benefit: localization of the application. Based on the browser's language, suitable message bundle file is used (EN or PL in above example).

So far so good - nothing new is here when comparing to JSF 1.x. But what about other resources like JS, CSS or image files? JSF 2.0 can handle those resources in a more intelligent way than before - a special ResourceHandler is used for load resources from some predefined locations. According to the documentation resources are expected to be placed in:

WebRoot/resources/<resourceIdentifier> 

WebRoot is a root of web application - in the Eclipse generated web projects it is the directory named "WebContent". Part resourceIdentifier have this structure:

[localePrefix/][libraryName/][libraryVersion/]resourceName[/resourceVersion] 

resourceIdentifier defines the subdirectory structure inside WebRoot/resources/directory. And the most important part: localePrefix means that resources can be localized based on the browser's language, like message bundles. Part libraryName can be use to group resources by their type in different directories, for example "css", "images", "scripts".

Let' see how it work in a sample application. As I wrote in previous post, we used shopTemplate.xhtml file as a template page for all pages in application. The second purpose of this file (next to defining reusable parts) is to separate the structure from the presentation - template page will include all CSS files and common images files. We will use new ResourceHandler in order to load some CSS and images suitable for current browser language:
  • images: we have two pictures (bike_logo.jpg and flag.gif) in sample application visible in the header - they will change depending on current browser language
  • CSS: depending on current browser language, different CSS will be loaded. The only difference between loaded CSS's is footer color (just to show that CSS is really changed)
According to the documentation we have to create directory structure for mentioned resources and put different resource there:


How to load such resources on the page? First we have to perform additional configuration to enable loading resources using proper localePrefix ("pl" and "en" on the screenshot above). We have to create a special localized entry named javax.faces.resource.localePrefix in a resource-bundle file. This file must be configured as message-bundle in faces-config.xml - we can not use resource bundles (used for localized messages as shown above) to put entry there:


Now we can use the resources on the shopTemplate.xhtml page:


Please note that we use here a new JSF 2.0 tag:
<h:outputStylesheet library="css" name="layout.css" />
Attributes library and name correspond to the libraryName and resourceName from <resourceIdentifier> respectively.

If we want to load  JS scripts we have to use additional JSF 2.0 tag: <h:outputScript ... /> wich has additional attribute named target - specifying where to render script link.

Loading images with standard tag <h:graphicImage ... /> is possible in two ways:
  • using attributes library and name correspond to the libraryName and resourceName from <resourceIdentifier> respectively (like for CSS)
  • using special EL expression "#{resource['images:bike_logo.jpg']}" (wartch out for letters: EL has resource word but in the WebContent there is a resources directory!)

Note about testing: in order to test if images and CSS (footer color) changes when browser language is changed, I recommend clean the browser cache and restart it completely before testing (sometimes image cache prevents from changing the image). The test result should be:

PL version:


EN version:


-------------------------------------------
Download source files:
The complete working example of mentioned application which will contain all described features, will be available in the last (third) article of this serie.
Sunday, October 17, 2010

JSF 2.0 - New features (part 1 of 3)

Note: below description uses Eclipse Indigo, Tomcat 7.0.28 and MyFaces 2.1.7. 

Requirements:
  • working "Hello World" example in JSF 2.0 as a basis (from here)
You will learn:
  • templating with Facelets
  • simplified page navigation
In the previous post I showed how to create classic "Hello World" application in JSF 2.0. The example was created in the simplest possible way. I focused on generating and setting up working and ready to use project in Eclipse. Created application did not differ much from similar "Hello World" applications in JSF 1.2, because I did not use JSF 2.0 built-in featues. Now it is a time to show what new features are in JSF 2.0 and how they can improve development web applications. 

Sample application:
In order to go higher than "Hello World" level we will create fully functional mini application which will serve as an example for mentioned JSF 2.0 features.
Let's assume that we are creating a web application for bicycle shop. Our application should present a list of available bikes. Bikes will be divided because of their type like MTB, Trekking and Cross bikes. In addition bike list will have a filter allowing to display only bikes with a special discount price. User should be able to display detailed information about selected bike from the presented list. We will use those pages in application:
  • bikesShop.xhtml - start page presenting information about bike shop
  • bikesList.xhtml - page presenting bikes of given type
  • bikeDetails.xhtml - page presenting detailed information about bike displayed on bikesList.xhtml
Under the hood we will use those classes:
  • BikeDataProvider.java - singleton, acts as service which belongs to business logic. Responsible for loading bikes of certain type and loading single bike with its details. For simplicity all bikes instances are created and stored inside that class.
  • Bike.java - a class from the model representing single bike instance. A list of bike instances is created and used inside BikeDataProvider.java.
  • BikeDetails.java, BikesList.java - managed beans used for bikeDetails.xhtml and bikesList.xhtml respectively. They call BikeDataProvider.java for loading bikes list or single bike.

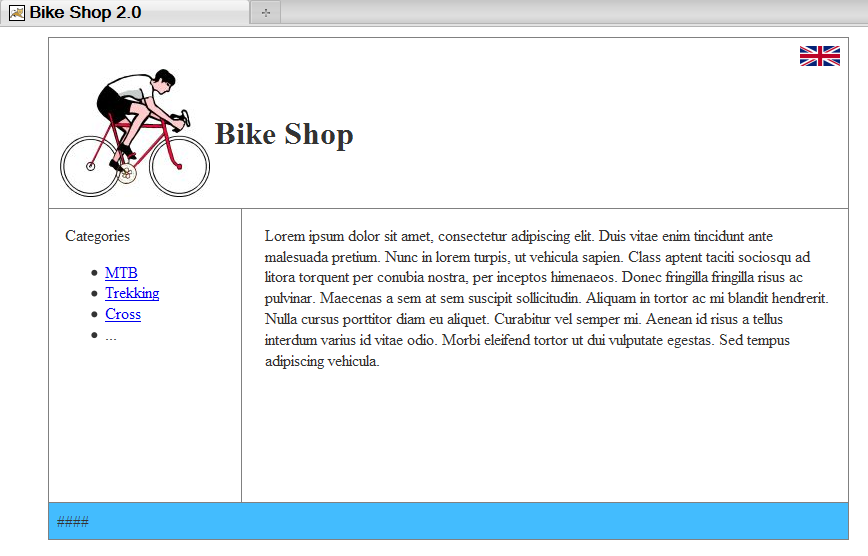
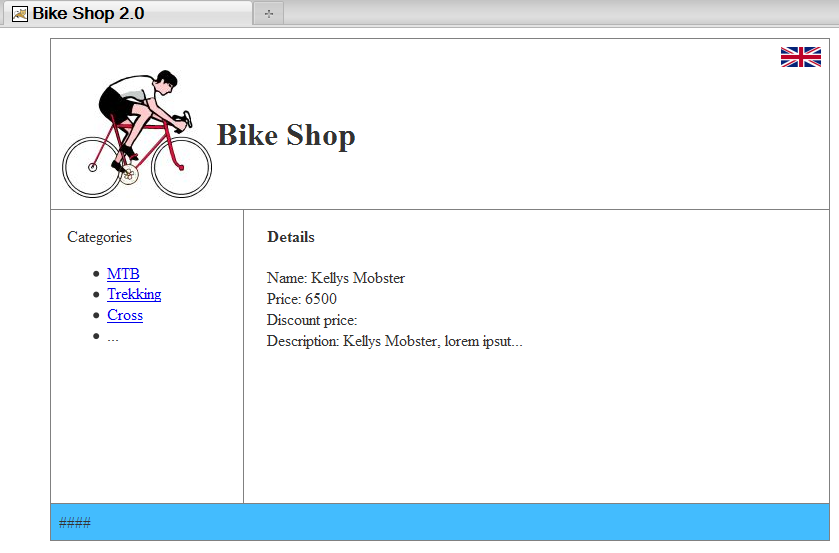
Web application will have popular and standard layout - header on top, menu on left, content on righ, footer on bottom. Header will have shop's logo and name, menu will have bike types listed, content will have some information about the shop and will display bikes list for given type, footer will be empty with some background color. The whole application will look like this:

bikesShop.xhtml:


bikesList.xhtml:


bikesDetails.xhtml:


Facelets - templating.
One of the key feature of Facelets is ability to create page templates. Have a look at our sample applications screenshot above - all of them have common content like header, left menu and footer. If we had JSF application based on JSP pages without using Facelets, those elements would be included separately into source code of each web page. Imagine small change in the header - it may become a maintenance nightmare because we have to change source code of all pages where header is visible. With the Facelets is it possible to extract common content and put it into one page template. The template has special sections where variable content will be displayed - pages which use the template "injects" to those sections their specific content.

For our application we will create a template page named shopTemplate.xhtml which will act as a template for three pages visible above (bikesShop.xhtml, bikesList.xhtml, bikeDetails.xhtml). The whole page layout common for all pages will be defined inside the single template page. This gives us another advantage - we can follow one of the best practises in designing web pages here - separate the structure from the presentation. The template will contain only the pages structure while the whole presentation will be placed in separate CSS file used by template. The source code for the template will look like this:
<?xml version='1.0' encoding='UTF-8' ?> 
<!DOCTYPE html PUBLIC "-//W3C//DTD XHTML 1.0 Transitional//EN" "http://www.w3.org/TR/xhtml1/DTD/xhtml1-transitional.dtd">
<html xmlns="http://www.w3.org/1999/xhtml"
      xmlns:ui="http://java.sun.com/jsf/facelets"
      xmlns:h="http://java.sun.com/jsf/html"
      xmlns:f="http://java.sun.com/jsf/core">
    
    <h:head>
        <meta http-equiv="Content-Type" content="text/html; charset=UTF-8" />
        <title>Bike Shop 2.0</title>
    </h:head>
    
    <h:body>
        <div id="container">
            <div id="top">
                <!-- logo and name goes here -->
            </div>
            <div id="leftnav">
                <h:form>
                    <!-- links goes here -->
                </h:form>
            </div>
            <div id="content">
                <ui:insert name="content" />
            </div>
            <div id="footer">
                ####
            </div>
        </div>
     </h:body>   
</html>

Please note the element <ui:insert name="content" /> inside the div named "content". It represents variable content which will be displayed in this place. Pages bikesShop.xhtml, bikesList.xhtml and bikeDetails.xhtml will "inject" here their content using special syntax. Let's have a look how bikesShop.xhtml page display its content using the template. Here is the code for bikesShop.xhtml:
<?xml version='1.0' encoding='UTF-8' ?>
<!DOCTYPE html PUBLIC "-//W3C//DTD XHTML 1.0 Transitional//EN" "http://www.w3.org/TR/xhtml1/DTD/xhtml1-transitional.dtd">
<html xmlns="http://www.w3.org/1999/xhtml"
      xmlns:ui="http://java.sun.com/jsf/facelets"
      xmlns:h="http://java.sun.com/jsf/html"
      xmlns:f="http://java.sun.com/jsf/core">
  <ui:composition template="shopTemplate.xhtml">
       
        <ui:define name="content">
         Lorem ipsum dolor sit amet...
        </ui:define>

  </ui:composition>
</html>

First note that bikesShop.xhtml page have no <head> or <body> tags - they are defined in the template. A special element <ui:composition template="shopTemplate.xhtml"> tells the page to use the mentioned template.
As I wrote, the template has a special section for inserting the variable content (<ui:insert name="content" />). The page bikesShop.xhtml defines content to be placed into that section by using the tag <ui:define name="content"> ... </ui:define>  - note that attribute name="content" is the same for  <ui:insert/> and <ui:define />. Pages bikesList.xhtml and bikeDetails.xhtml use the same mechanism (they have the same <ui:define /> tag in their source).
That's all about templates.

Simplified page navigation.
Every page navigation in JSF 1.x required a proper entry in faces-config.xml file. It was something like this:

<navigation-rule>
     <description>Welcome page to message page</description>
     <from-view-id>/index.jsp</from-view-id>
     <navigation-case>
       <from-outcome>helloMessage</from-outcome>
       <to-view-id>/message.jsp</to-view-id>
    </navigation-case>
   </navigation-rule>

JSF 2.0 provides a simplified navigation model - we do not need any entries (navigation rules) in the faces-config.xml file. Why?
Suppose we have a method used for navigation which returns some string value. This string value (known as outcome) is taken by a navigation handler and the handler checks for navigation rules in faces-config.xml which have defined the same from-outcome value. When the rule is found, it is applied and a proper navigation is done. This is how it worked in JSF 1.x and how it works in JSF 2.0. But JSF 2.0 navigation handler does additional operation here: if no matching from-outcome value is found in faces-config.xml (in other words: there is no navigation rule to apply), handler checks also existing pages names (view identifiers). If existing page name matches returned outcome value, the navigation is done to that page.
For example if we have a navigation method in some backing bean:
public String getBikes(){
   bikesList = ... // load some bikes
   return "bikesList";
}
and there is a page named bikesList.xhtml, invoking this method will cause the navigation to that page - without defining proper navigation rule in faces-config.xml.

-------------------------------------------
Download source files:

The complete working example of mentioned application which will contain all described features, will be available in the last (third) article of this serie.
Wednesday, September 15, 2010

JSF 2.0 - "Hello World" in Eclipse (with *.xhtml pages)

Note: below description uses Eclipse Indigo, Tomcat 7.0.28 and MyFaces 2.1.7.


Requirements:
  • installed Java (description here)
  • installed and configured Eclipse (description here)
  • installed and configured Tomcat for the Eclipse (description here)
You will learn:
  • how to create "Hello World" application in JSF 2.0 using Eclipse
Note 1: The following post and example show classic JSF 2.0 application with a view technology as .xhtml pages. I do not use any additional libraries and extensions for the standard JSF libraries. I don't use (for the time being) templates. JSF implementation used comes from MyFaces.

Note 2: I use standard capabilities of IDE platform to generate the project, without those thousands automated plugins which do everything for the user. Sometimes configuration and usage of a plugin is a "pain in the ..." - in my opinion it is worth to know how to deal with a standard set of tools, and after that there is always a time to faciliate our life ;-)

In this post I will show how to create sample JSF 2.0 application using Eclipse. It will be similar application like in the post about creating sample JSF 1.2 application. But there will be some small differences, especially during generating the project and adding JSF capabilities to it. Let's do it.

Step 1: create new dynamic web project for the Tomcat. It is available in "web" menu section under option "File->New->Project":


Press "Next" to go further and set some basic project's properties:


Step 2: adding JSF capabilities for the generated project (JSF and JSTL libraries).

This step is the same as step 2 in previous JSF 1.2 example under Eclipse. Just copy all necessary .jar libraries into WebContent\WEB-INF\lib directory.

Also here there is a possibility to use Code Assist for *.xhtml pages. Unfortunately there is one difference comparing to support for JSF 1.2.x - You can click on bean/field only when Your beans are directly declared in faces-config.xml file. If Your beans are declared with the help of annotations, it does not work. This is Eclipse bug (see for example https://bugs.eclipse.org/bugs/show_bug.cgi?id=323709). It is still not fixed in Indigo, despite the fact that it should work in 3.4.x, as noted in the bug.

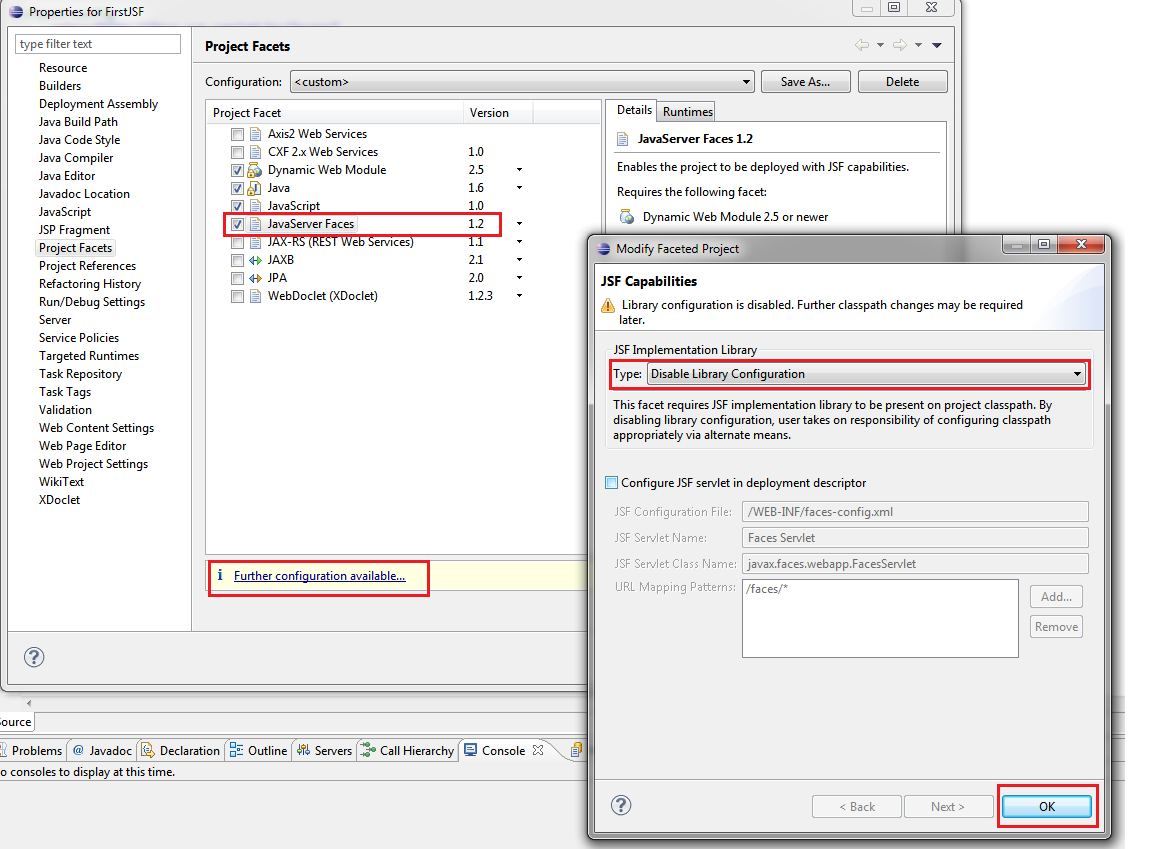
In order to enable Code Assist just open context menu and choose "Properties" option. Locate the section "Project Facets" and check the option "JavaServer Faces". Then "Further configuration available...". On the screen You have to select "Disable library configuration" and press OK:


Step 3: the project structure is ready. Creating sample application.

This will be the same application as for version 1.2 with some differences coming from JSF 2.0:

- pages extenstion will be .xhtml instead of .jsp
- we use annotations in backing beans
- there will be no faces-config.xml file (now)

Everything should look like this:


File web.xml has to be changed like shown on screenshot below:


Step 4: deployment and running.

This step is similar to steps 6 and 7 from JSF 1.2 version. After deploying application on the server and starting the server, we have to open a browser and type in URL:

http://localhost:8080/FirstJSF2

That's all. We should have working JSF 2.0 application.

-------------------------------------------
Download source files:

Note: make sure that Java, Eclipse and Tomcat are properly installed and configured for running the project (additional configuration may be required if different directories are used).

Eclipse complete sample project is here (with all required libraries). You can also download a war file located here (just copy it inside webapps folder in Your Tomcat and start Tomcat with the script startup.bat)

Wednesday, September 01, 2010

JSF 1.2 - "Hello World" in Eclipse (with *.jsp pages)

Note: below description uses Eclipse Indigo, Tomcat 7.0.28, MyFaces 1.2.12 and JSTL 1.2.1. 

Requirements:
  • installed Java (description here)
  • installed and configured Eclipse (description here)
  • installed and configured Tomcat for the Eclipse (description here)
You will learn:
  • how to create "Hello World" application in JSF 1.2 using Eclipse
Note 1: The following post and example show classic JSF 1.2 application with a view technology as .jsp pages. I do not use any additional libraries and extensions for the standard JSF libraries.

Note 2: I use standard capabilities of IDE platform to generate the project, without those thousands automated plugins which do everything for the user. Sometimes configuration and usage of a plugin is a "pain in the ..." - in my opinion it is worth to know how to deal with a standard set of tools, and after that there is always a time to faciliate our life ;-)
Many publications and tutorials about JSF (Java Server Faces) very briefly descibe the configuration of development environment for the described examples. Many times I saw such situation: after few sentences about "how amazing is JSF" there was a simple list of JSF tags with their attributes described. Or at the beginning there was an example of "Hello World" application and every line of code was described and explained.
I think that is what is missing is the lack of an example of complete project with its directory structure and an information how to create this project and deploy on the web server. I saw some examples where the project structure was shown, but for the building and deploying application user had to use Ant and type some commands. Great, but we need Ant, when we have Ant, we need to be familiar with it to write build.xml file, then we need something else and so on and so on.
This is of course OK if we want to write everything from scratch by hand. But wouldn't it better just to start our IDE, make some clicks and have a complete and working project ready for further development?
Let's see how it looks like in Eclipse IDE.

Step 1: creating dynamic web project for the Tomcat.

Open menu "File->New->Project" and in the "web" section find and choose "Dynamic Web Project" and press "Next":
 

Press "Next" to go further and set some basic project's properties:


After that we should have generated project structure for the web application.

Step 2:
adding JSF capabilities for the generated project (JSF and JSTL libraries).

The easiest way is to download latest libraries of MyFaces 1.2.x from here and JSTL 1.2.x from here, and copy all .jar files into generated WebContent\WEB-INF\lib directory. After that just refresh the whole project by pressing "F5" on the project's root and all libraries should appear in the section named "Web App Libraries" in the project's structure.

In addition it is worth to enable nice feature named Code Assist. Code Assist allows automatically complete JSF tags when typying by pressing CTRL + Space. It also provides direct access to beans, their methods or fields directly from JSP page - just by click on bean/field name. In order to do this just right click on the project and from the opened context menu choose "Properties" option. Locate the section "Project Facets" and check the option "JavaServer Faces". Then "Further configuration available...". On the screen You have to select "Disable library configuration" and press OK:


Note: project facet "JavaServer Faces" allows to download JSF libraries automatically and add them to the project. Unfortunately JSTL libraries still needs to be downloaded manually.


Step 3: the overview of a project.

When steps 1-2 where done as described, the project structure should look like this:


Step 4: "Hello World" application.

Now we are ready to implement some sample JSF application. First we should create a package named com.firstjsf.backingbeans in the "src" directory. Second we should create two classes inside the package named HelloMessageBean and WelcomeBean. Third we should modify generated faces-config.xml file by adding there our classes and navigation rules. Everything should look like this:


Be careful about small and big letters - names should be exactly as shown above. In the faces-config.xml file we created entries for the navigation rules for not existing yet web pages. Let's create those web pages (index.jsp and message.jsp) in the WebContent directory:


Application is ready.

Step 5: deploying on Tomcat.

At the bottom of a screen locate "Severs" tab. We should have already Tomcat there. Right click on server name to open its context menu, ten choose option "Add and Remove...":


Choose our project and add it to the server by pressing "Add" button:


Step 6: running the application.

Go back to the "Server" tab again and make sure that our project is visible on the server. Then click the marked icon to start the server:


After starting the server we should see that the server state was changed:


After deploying application on the server and starting the server, we have to open a browser and type in URL:

http://localhost:8080/FirstJSF

What next? This simple working project can be used as a base for further learning about JSF. For example we can change the view technology from .jsp to facelets. We can add libraries which extend our standard tags by adding tags with ajax support, i.e RichFaces.

-------------------------------------------
Download source files:

Note: make sure that Java, Eclipse and Tomcat are properly installed and configured for running the project (additional configuration may be required if different directories are used).

Eclipse complete sample project is here. External libraries folder (with JSF and JSTL) is here. You can also download a war file located here (just copy it inside webapps folder in Your Tomcat and start Tomcat with the script startup.bat)

Wednesday, February 24, 2010

"My databse is slow" - part 3: some technical stuff

Note: below description uses PostgreSQL 8.3.7.

In the previous two articles I tried to show what can affect the overall performance of the database and how important are indexes.
If we assume that the database is normalized, memory settings for the server are ok and we have indexes, the only way to check the performance is monitoring the query plans. Therefore I would like to return once again to the query plans and look at them with more details.

From the previous post, we know that we can generate plans for queries using two commands. These commands are:
  • EXPLAIN SQL_command
  • EXPLAIN ANALYZE SQL_command - this command is a variant of the first with small difference: examined query is executed and EXPLAIN ANALYZE returns the real execuion time.
Using the test database from the previous post, let's see the query plan for the following SQL command:

select * from customers where lname = 'Cervantes';

To see the query plan, execute those two commands:

vacuum analyze;
explain select * from customers where lname = 'Cervantes';

Query plan that has been generated for this query is as follows:


Always we are most interested in "the highest" line of displayed plan - it shows the total cost of the query execution, after all other internal operations for more complex queries (eg joins, sorts, etc.).

In our case we have: (cost: 4.51 .. 59.47 rows = 33 width = 18). What does it mean?
  1. cost: 4.51 .. 59.47 - this is an interval defining total execution time measured in special units called disk page fetches - these units are not seconds nor other units of time. First number estimates time needed to retrieve first row in the result, second estimates total cost of returning all rows in the result. The calculation of this value is "higher mathematics", especially if the query uses more techniques than primitive table sequential scanning - which is the easiest and can be easily calculated. Unfortunately, but only for primitive examples like "select * from some_table" (without the use of indices to be 100% sure that the scan will be performed sequentially and without any query conditions "where"), You can find over the Web some examples of calculating these values. Those who are interested in more details and technical stuff, should visit this page
  2. rows = 33 - this is estimated number of rows returned by a query.
  3. width = 18 - this is estimated size (in bytes) of all the returned rows

Above data are obtained on the basis of statistics located in a special system tables. There are two tables of statistics which are crucial for the query planner:
  1. pg_class - contains information about certain database relations (tables, indexes, etc.), i.e. their location and size.
  2. pg_stats - contains information about the data stored in tables, i.e. the most common values, the frequency of common values occurrence.
Let's see what are the statistics for the table "customers", and what is their impact on some elements of the query plan for above query about user "Cervantes".


Returned data mean that the table "cutomers" has 10.000 records and is located on 62 "pages".


Returned data are based on some statistical data for all the columns in the table "cusotmers" and their content. It is specified which values are most popular, what is their frequency, and amount of values which are different from each other.
What is the meaning of this data in the context of our query about "Cervantes" user?

pg_class - is the basis in calculating the cost of the query execution. For our "Cervantes" query  in the case of sequential scan (if there were no index on the "lname" field in the Customers table), we would calculate the cost from the formula:
(relpages * SEQ_PAGE_COST) + (reltuples * CPU_TUPLE_COST) + (relpages * CPU_OPERATOR_COST)
Capitalized names are costs of arbitrary operation - the are defined in postgresql.conf. Unfortunately (or "fortunately"), our query uses indexes, so the calculation of the cost is a bit more complicated (task for volunteers, formulas are here, You only have to to be familiar with the concepts of "last recently used buffers" (LRU) and Mackert-Lohman formula ;-)).

pg_stats - allows to estimate the number of rows returned in a query using given logical condition (in our case: "where lname = 'Cervantes'"). In our case for the "Cervantes" query we are lucky - "Cervantes" occurs directly in the list of most common surnames, and also is known for its occurrence. The number of rows returned is calculated using the formula:
relpages * selectivity
where:
selectivity = most_common_freqs["Cervantes"]
Hence we get:
10000 * 0,00333333 = 33
And what if we are looking for value which is not in the column "most_common_freqs"? Then the formula has a different form:
selectivity = (1 - sum(most_common_freqs))/(num_distinct - num_most_common_vals)
Calculating selectivity value for the name "Smith", I leave for volunteers as usually ;-). Remember that first You have to execute "vacuum analyze" and then view statistics and then the query plan.

-------------------------------------------- 
Some notes about the statistics:

The content of statistics tables is generated based on random samples taken from the tables in the database. Generating (and therefore refreshing) full statistics takes place during the execution of the VACUUM ANALYZE command. Hence, it is very important to run this command periodically to ensure that statistics for the planner are up to date. Therefore, before showing the above example the first command executed by me was VACUUM ANALYZE in order to query plan be based on the most reliable statistics.
It should be noted that next execution of this command can generate a slightly different statistics, so query plan for the same query may be slightly different (in terms of cost and estimated number of rows). This is because of mentioned random samples taken for calculations.

--------------------------------------------
A few final notes about performance

I can say that the general rule to optimize query execution time is as follows:
"There is no certain way to increase performance in all cases. The best method is trial and error."
In practice it means to try to generate different query plans (in addition to that which is generated by default) and select those with the best execution time. These attempts usually involve forcing the query planner  to behave in different way which leads to a different query plan. This can be achieved through:

1. Forcing the query planner to use an index (often the index exists but is not used by the planner). This can be done for example by:

  • switching off a global sequential scans by setting enable_seqscan = off in postgresql.conf file
  • partial indexes (conditional) - You can create a conditional index for the most frequently returned data in column
  • indexes using multiple fields (watch out for the order - the order of fields in the index should be the same as the order of fields in queries)
  • some SQL tricks related to change the query selectivity, for example using LIMIT, ORDER BY or trailing condition AND TABLE_ID = TABLE_ID (where TABLE_ID is a master key in the table)
2. Changing the order of joining multiple tables, for example executing "(A join B) join C" can be different than executing "A join (B join C)" - this is similar to a problem of  "optmial matrix-chain multiplication".
3. Using stored procedures, views, breaking huge query into a number of smaller queries .

Interesting fact (found over the Web):
In order to monitor the progress of executing a long query to the database (a really long time, not a few seconds) you can create a sequence with the value set to 1 (eg, the sequence "monitor_seq") and add it to executing query:


select nextval('monitor_seq'), column1, column2....

Executing:

select currval('monitor_seq');

at the time of running the long query will show us the progress.

Tuesday, January 05, 2010

"My database is slow" - part 2: indexes.

Note: below description uses PostgreSQL 8.3.7.

This article is a continuation of previous one about database performance.
Suppose we have a database that is normalized to our needs, the memory of the server was also quite reasonably allocated, we are using a connection pool and we did not change the default transaction isolation level for our database - but the database still is not a "speed daemon". What can You do in this situation? Did we miss something?

You can look inside the database giva a closer look on specific operations performed on the data to determine which operations cause performance degradation and possibly "help" them perform faster. As the sample database I will use PostgreSQL - I will examine its specific mechanisms to check and improve performance. This will be only an outline of what can be done (based on crude example), because the topic is so large that it may well be placed on a separate dedicated blog.

Requirements:
  • installed PostgreSQL (description here)
  • a test database with sample data - just to show how PostgreSQL performs a very simple SQL opeartions
Let's consider a very simple database for some online store with two tables: customer table (called Customer) and customers' orders table (called Order). Just open pgAdmin and execute this SQL command:


CREATE DATABASE store ENCODING = 'UTF8';


Then connect to database "store" and run this SQL commands:


CREATE TABLE customers
(
customer_id INTEGER,    
fname VARCHAR(32),
lname VARCHAR(32) NOT NULL,
CONSTRAINT customer_pk PRIMARY KEY(customer_id)
);

CREATE TABLE orders
(
order_id INTEGER,
customer_id INTEGRE NOT NULL CONSTRAINT customer_order_fk REFERENCES customers(customer_id),
description TEXT,
price NUMERIC(7,2),    
CONSTRAINT order_pk PRIMARY KEY(order_id)    
);

For simplicity, here I do not use a SERIAL field to hold primary keys - just ordinary integer with constraint. Now we should fill the database with some sample data: lets put about 10 000 records to Customers table and 30 000 records to Orders table.  That is rather huge amount of data. How can we do it?
The best way is to write a Java program that generates a file with proper SQL INSERT statements for each table - this is homework for You ;-)
I wrote simple program which takes popular first names for males and popular first names for females, then takes popular surnames from here and combines them together to produce 10.000 "people". Having those records and knowing their customer_id (that's why I used ordinary integer field - just to write a program) my program generated random 30 000 orders for those customers.

And now suppose we want to retrieve all customers named Smith and we want to see all orders for each customer Smith. We need two queries:


select * from customers where lname = 'Smith';
select * from orders join customers on orders.customer_id=customers.customer_id where customers.lname = 'Smith';

In my case, the first query returns just 9 customers named Smith (from total of 10 000) and 30 orders (from total of 30 000) for all 9 "Smiths".

Okay, we have SQL commands - but how can we check their execution time on a database? PostgreSQL provides two commands that show details about executed commands:
a) EXPLAIN SQL_command
b) EXPLAIN ANALYZE SQL_command - this command is a variant of the first with small difference: examined query is executed and EXPLAIN ANALYZE returns the real execuion time.

Before we show an example of above commands execution, some technical information about the process of executing the query by PostgreSQL: when the PostgreSQL server receives SQL command from client application, the query string is passed to the query parser that checks for syntax errors. If everything is ok, parser based on the query creates a structure called the query tree. Then, this structure is passed to the query planner which generates all possible query plans and chooses the shortest one from them. This plan is passed to the executor who performs the query and returns the records in the manner described in query plan.
Mentioned EXPLAIN command displays the details of the plan chosen by the planner as the shortest one. Let's see the result of executing EXPLAIN ANALYZE for the queries about users Smith:


Because reading query plans and their details is a separate art, we will focus on the actual run time (visible as a Total Runtime, respectively 1,482 ms for the first question, and 16,552 ms for the second question).

Lets provide indexes for the fields we are searching for and for the fields where the join operation is performed. In our case it will be:
a) the lname column of the Customers table - create index with the command: 

CREATE INDEX lname_index ON customers USING btree (lname);

b) the foreign key column in Orders table (the column cutomer_id) - create an index using the command: 

CREATE INDEX customer_fk_index ON orders USING btree (customer_id);

Note:
After You create indexes, You have to refresh the statistics used by database planner to calculate the optimal query plan. This is done by running VACUUM ANALYZE command. After executing this command, once again execute the EXPLAIN ANALYZE command for our "Smith" queries:


The results of the queries which are several times faster than previously. They are respectively: 0,123 ms (1,482 ms previously), and 0,507 ms (16,552 ms previously).

The advantage is obvious. But whether the index will solve all our problems? Not always. There is no guarantee that the planner will benefit from the index. Sometimes it appears that the sequential table scan can be faster than using an index (such behavior may depend on the "selectivity" degree of certain query). In most cases it is good to have indexes - they can only help.